← Work · Multi-agent AI
Identifood
A four-agent pipeline that turns an ingredient list into a rating that helps a shopper make informed dietary decisions, built in a one-week course to demonstrate what four narrow agents do with a problem that renders a large prompt ineffective.
The Problem
Reading a label rarely produces understanding. Most people cannot identify half of the chemical names, and fewer can say what those names mean for their own health. A food that suits one person's diet can work against another's. Moreover, what one person eats daily without consequence may affect another differently, depending on weight or health condition.
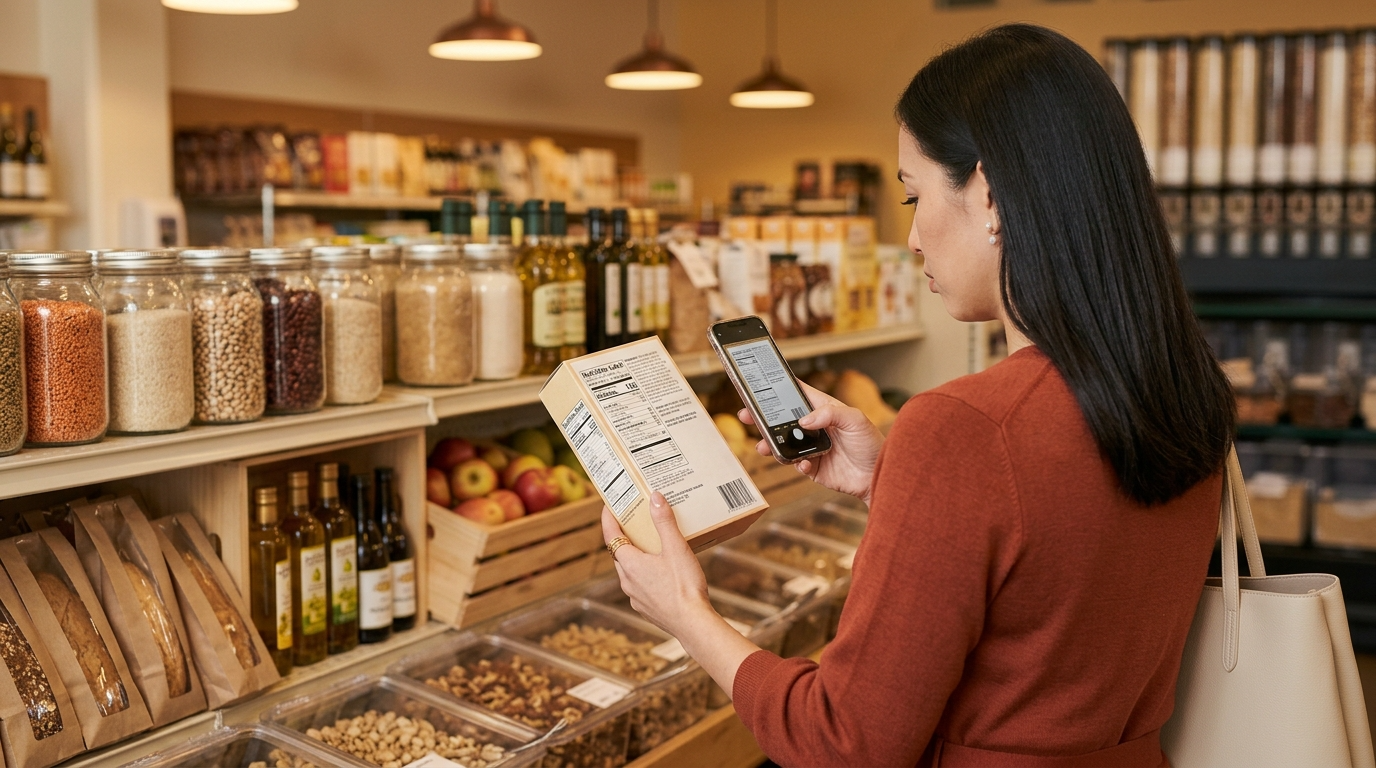
Identifood reads a food label and tells a person what the information means for them. A shopper holds a package in the grocery aisle, scans the ingredient list, and receives a health rating from one to five along with a sense of how often this food item should be consumed in their week.
One Prompt, Four Jobs
A second technical problem influenced this project's design. A single large prompt could be asked to read the label, judge the ingredients, account for the person, and return a verdict in one pass. However, a prompt asked to manage everything at once tends to lose nuance. When one prompt makes every judgment, a reader struggles to separate the well-reasoned steps from the failures. Ultimately, a health tool whose reasoning cannot be examined is difficult to trust, and trust is a critical piece of the experience.
More on the problem
Diabetes makes the asymmetry concrete. Sugar does not mean the same thing for every person who reads the same label. Therefore, a system returning one verdict for every reader has already failed the person who relies on this information. The diabetic user became the recurring example through the build and the example driving the personalization stage.
The Pipeline
A sequence of four agents formed the system, with each agent receiving a clear input and handing a clear output to the next. Based on the course's terms, it is a sequential pipeline, or an assembly line of specialized agents, where one agent's structured output becomes the next agent's structured input.
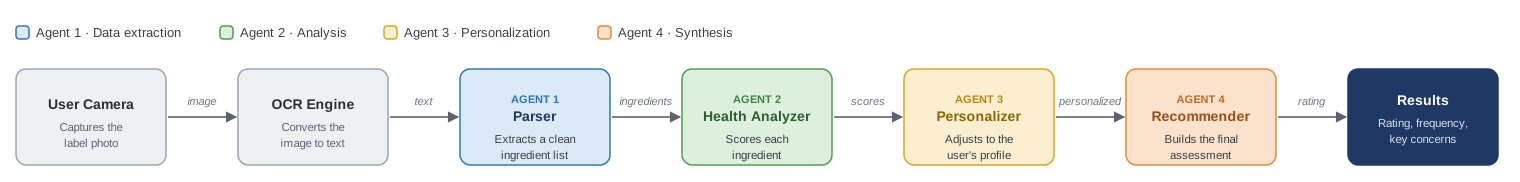
A horizontal pipeline of seven stages reading left to right. User Camera captures an ingredient list photo, which passes as an image to an OCR Engine that converts it to text. The text flows to Agent 1, the Parser, which extracts a clean list of ingredients. That list flows to Agent 2, the Health Analyzer, which scores each ingredient for health impact, for example water plus one and sugar minus two. The scores flow to Agent 3, the Personalizer, which adjusts them against the user's health profile, for example sugar minus three for a diabetic user. The personalized scores flow to Agent 4, the Recommender, which generates the final assessment. The pipeline ends at a Results Display showing a rating out of five, a consumption frequency, and key concerns.
Four Agents In Order
A phone camera captures the ingredient list as an image, and an OCR engine converts that image into raw text. The Parser then reads the messy text and extracts a clean list of ingredients. The Health Analyzer scores each ingredient in isolation, marking water as a small positive and sugar as a negative. The Personalizer bends those general scores toward the individual, lowering sugar further for a diabetic user. The Recommender gathers the personalized scores and produces the final read, a rating and a consumption frequency for that person.
Each agent does one job and passes its output to the next.
More on the pipeline
The pipeline ran on one model, Gemini 1.5 Flash, called through the
google-generativeai library. Google AI Studio served as the place
to test and refine each prompt, and a Kaggle notebook served as the
runtime. Consolidating to one low-cost model kept the project
buildable inside the course budget.
The build labeled the agents by their roles. Agent 3 held the working title Condition Filtering Agent and Agent 4 the Recommendation Agent, while the public documents use Personalizer and Recommender.
The Four Contracts
Each agent has one authored prompt written to a strict role, with a defined input and a JSON output that becomes the next agent's input.
- The Parser takes raw text and returns a clean ingredient list.
- The Health Analyzer takes that list and returns a score and a reason for each ingredient.
- The Personalizer takes the scores and a user profile and returns adjusted scores with the reason for each change.
- The Recommender takes the personalized scores and returns a rating, a consumption frequency, a plain-language explanation, and suggested alternatives.
The Comparison
The course asked for the single-prompt approach to be written out and compared with the multi-agent one. The team wrote it in full and kept it as a reserve path, a single Gemini call instructing one model to simulate all four agents in one response. This path existed in case four separate stages proved too slow or too costly inside the time budget. It was not necessary because the built pipeline used four distinct agents.
| Dimension | Single prompt | Four-agent pipeline |
|---|---|---|
| Ingredient extraction | Sometimes misses items | The Parser catches all |
| Health scoring | Vague good or bad | Specific scores with reasons |
| Personalization | Generic advice | Condition-specific adjustment |
| Explanation quality | High sugar is bad | 12g sugar is 40 percent of the daily limit |
| Consistency | Varies across runs | Reproducible across runs |
| Debugging | A black box | Each step can be seen |
| Modularity | One monolith | Four independent modules |
| Extensibility | Rewrite the whole prompt | Add an agent without disturbing the rest |
When each agent holds one responsibility, each can be examined on its own. This ensures that a fault stays visible where and when it occurs. The health logic that bears the most responsibility exists in one identifiable place.
While a single prompt would have been faster to write and lighter to run, the pipeline asks for more parts and more coordination. Nonetheless, the pipeline buys a system whose reasoning can be seen, trusted, and improved one piece at a time.
A health tool whose reasoning cannot be examined is difficult to trust.
More on the comparison
The comparison also produced a chart drawn in the notebook. The team wrote the chart's percentages, including the consistency figures, to illustrate the case for the pipeline. A pipeline run did not produce those numbers.
The Trace
The course asked for structured execution traces, a timeline, and complete capture of the agent interactions. The logging framework built to answer those requirements became the most reusable piece of the work.
Four Pieces, One Trace
- An
AgentTypeenum names the four agents. - An
AgentExecutionrecord captures, for one agent, its name and type, a timestamp, the input and output data, the processing time in milliseconds, a success flag, and any error message. - An
ExecutionTracerecord gathers, for one run, a trace identifier, the start and end times, the total time, every agent execution, and the final output. - An
AgentLoggerdrives the run, marking each agent's start, recording each completion with its timing, and logging every handoff between agents.
Both records convert to JSON, a plain text format, so a whole trace can be saved to a file and read straight through. A separate routine displays the same trace as a timeline.
The demonstration that ran was a simulation. The main runner walked the four stages using hardcoded representative outputs and a short delay at each step, then logged the full trace, and it did not call Gemini. The four agent prompts, the architecture, and the logging framework were complete. In keeping with a project that worked from theoretical scenarios, the executed demonstration fed pre-written outputs through the logger to produce a readable trace.
More on the trace
The one remaining live model call is part of the reserve single-prompt path, not the four-agent design.
Against live calls, the same logging framework would capture the true timings without any change. The writeup recorded an execution profile with a total execution time, per-agent averages, and a full parse of the structured output. Because the demonstration ran through the simulation runner with hardcoded outputs and fixed delays, those figures describe the simulation and not live model latency.
Scope and Results
Identifood met the four capstone requirements. It delivered the architecture diagram, the writeup, the execution logging, and the single-prompt comparison, and Kaggle marked the completion with a badge. The work concluded at the end of that stage.
Scope Limits
Four scope facts define the limits of the result.
- OCR was not part of the executed pipeline. Sample label text went in directly, since the work stayed with theoretical scenarios.
- An ingredient database was not part of the build. The Health Analyzer scored each ingredient from the model's own knowledge, with the diabetic case as the recurring example.
- Live health profiles were not tested. The personalization ran on theoretical profiles, the diabetic user among them.
- The demonstration was a simulation. The four agent prompts and the architecture were complete, and the run fed pre-written outputs through the logger to produce its trace.
The documentation treats that scope as a feature of the record. A live build would read the photograph with Tesseract through pytesseract, an open-source OCR engine.
More on what it led to
The lasting value of Identifood was a beginning more than a product. I joined the course with no knowledge of multi-agent systems and left having helped build a working one. After the requirements were met, we assessed the potential for continued work. The estimate was that roughly six months of undivided attention separated the demonstration from a finished product. We also found a company that had already brought a near-match product to market. That discovery, together with the course's purpose as an introduction to the field, led us to conclude at this stage.
Three Insights
- Separation of concerns is helpful. It allowed four narrow agents to stay legible where one broad prompt becomes a black box.
- Validation belongs in code. Parsing and checking each handoff catches a malformed response at its source.
- Cost discipline directs design. An affordable model that ships beats the capable one that never ships.
Accessibility
Identifood does not include accessibility work. The build predates the practice this portfolio documents, and the executed demonstration produced console output in a notebook without an interface. The specific work needed includes:
- Accept a typed product name with the photograph, making the camera one of several routes to a rating.
- Write reading level into the Recommender's prompt as an output requirement, then check it with a readability formula for the lower secondary level.
- Expose the rating out of five as text before color, so perception has more than one channel.
- Offer the per-ingredient scores as a table or chart that works with a screen reader.